Data structures
A data structure definition (DSD) describes the columns of an indicator's data: the name, label, data type and role of each column, and the codelist it uses. NADA uses it to read uploaded data and to build the chart, filters, table and Data API of each indicator.
One data structure can be shared by many indicators. For the column roles, the series key and time period formats, see Key concepts.
Using the Metadata Editor?
Create data structures in the Metadata Editor. They are sent to NADA when you publish. Use these screens to check them.
Three ways to create a data structure
| Way | When to use it |
|---|---|
| Import JSON | A data structure exported from the Metadata Editor, or written by hand or by a script. Codelists can be included. |
| Import SDMX XML | A structure file published by an SDMX agency (OECD, Eurostat…), in SDMX-ML 2.1. Creates the data structure and its codelists. |
| Add data structure | Build it column by column in NADA |
The API equivalents are POST api/admin/data_structures/import_json and POST api/admin/data_structures/import.
The data structures list
Go to Settings → Data structures. The list shows each data structure's Title, Name, Agency, Latest version, number of Versions, number of Projects (indicators) that use it, IDNO and Status.
Click the number in Projects to see which indicators use a data structure. Check it before you change a data structure: every indicator that uses it is affected.
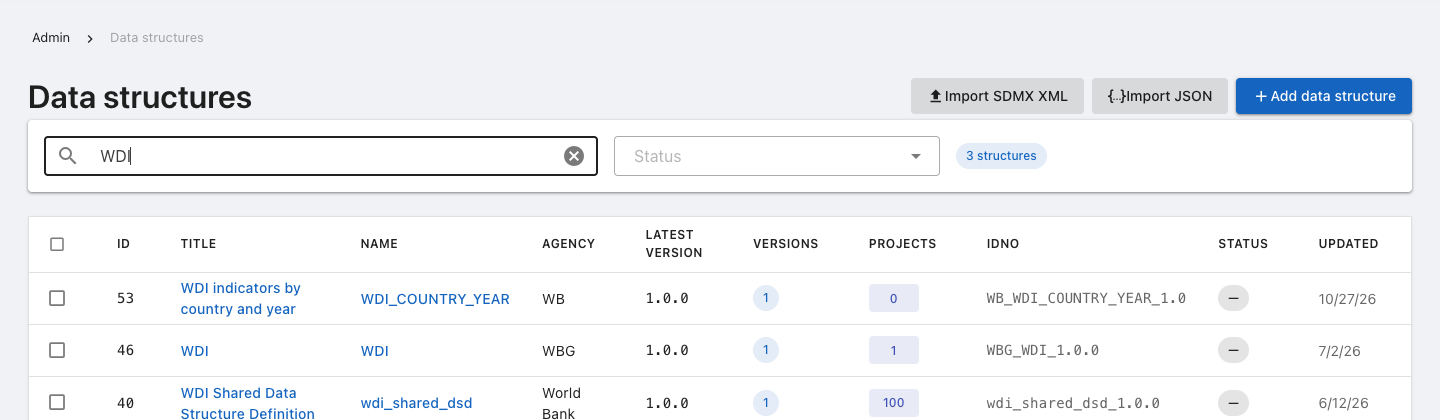
Import a data structure
From JSON
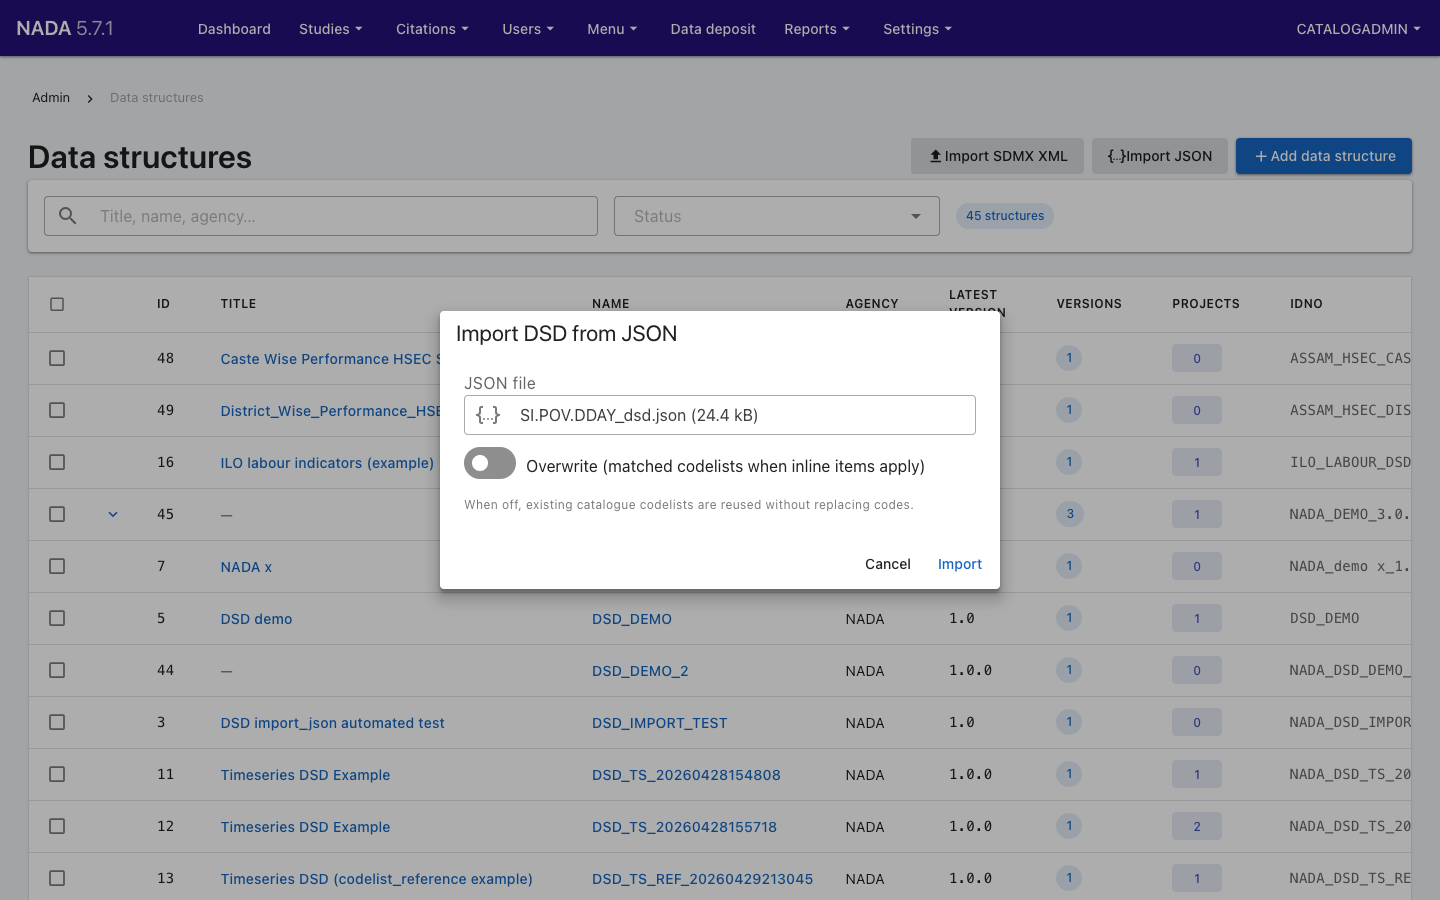
- Go to Settings → Data structures and click Import JSON.
- Choose the JSON file, for example
SI.POV.DDAY_dsd.jsonfrom the indicator sample. - Leave Overwrite off, unless you want to replace the codes of codelists that already exist.
- Click Import.
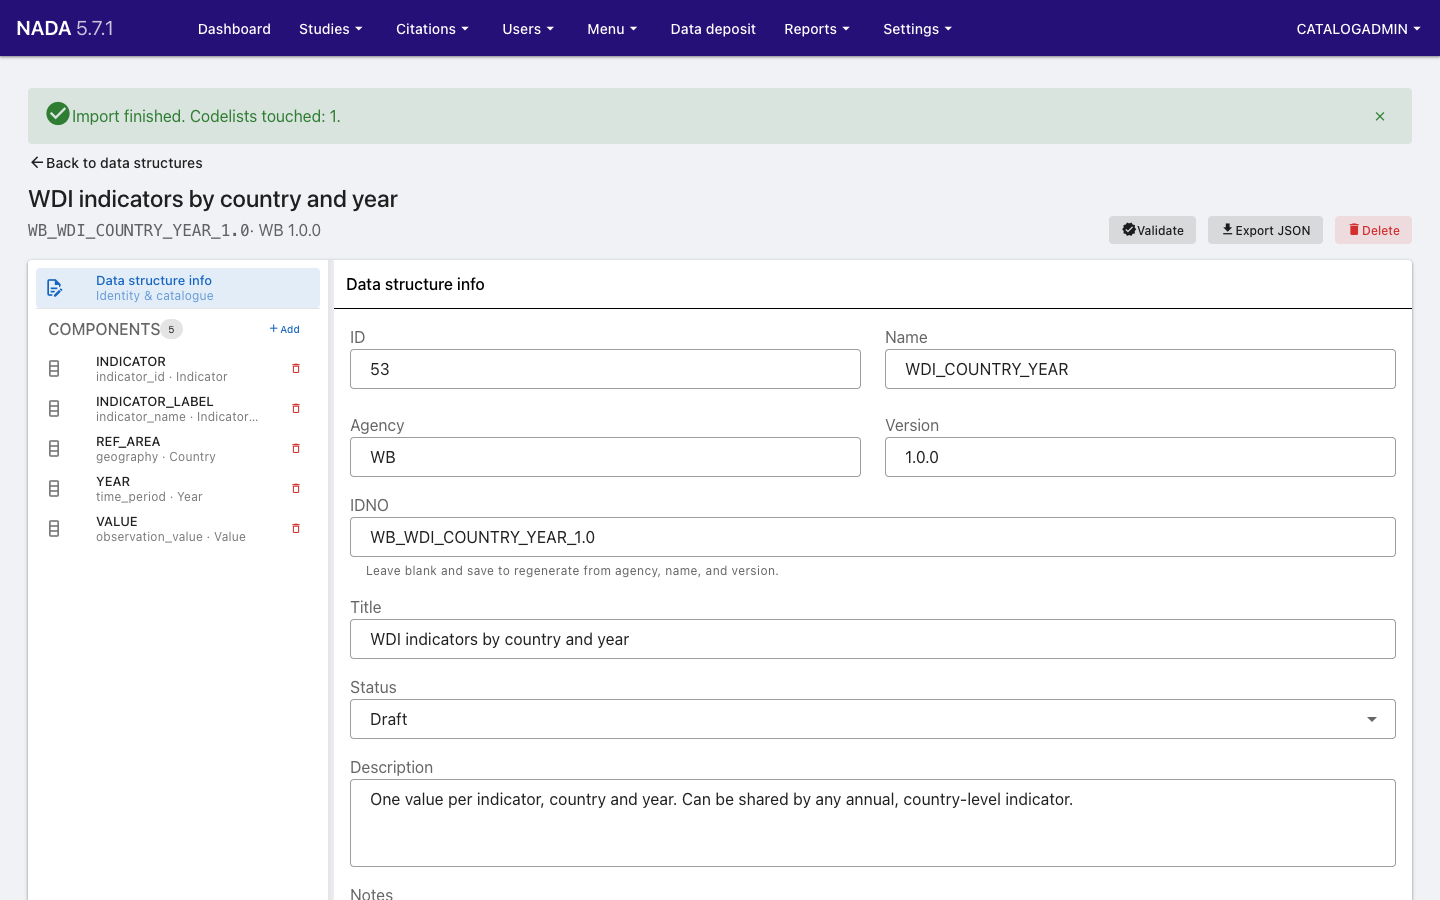
NADA shows Import finished. Codelists touched: … and opens the new data structure. Its status is Draft. A version such as 1.0 is stored as 1.0.0; the IDNO stays as in the file.
The file creates the data structure and any codelist it includes. A codelist that already exists with the same IDNO is reused. If a data structure with the same IDNO, or the same agency, name and version, already exists, the import is rejected.
Attribute codelists
Importing JSON currently keeps codelists on geography, dimension and periodicity columns only. A codelist on an attribute or measure column is left out. Attach it afterwards in the data structure's column editor.
From SDMX XML
- Click Import SDMX XML.
- Choose the structure file (SDMX-ML 2.1).
- If the file has more than one data structure, enter the one to import in Data structure id.
- Turn on Overwrite existing codelists only to replace the codes of codelists that already exist.
- Click Import.
Add a data structure by hand
Click Add data structure and fill in:
Field Description Agency The organization responsible. Default: NADA.Version Default: 1.0.0.Name A short identifier, unique for the same agency and version. IDNO Leave it empty to generate it from agency, name and version. Indicators refer to the data structure by this IDNO. Title A readable title, such as WDI indicators by country and year. Status, Description, Notes Optional. Save. The data structure opens, with its Components (columns) on the left.
Add the columns
For each column of the data:
In Components, click Add.
Fill in:
Field Description Name The column name, as in the data file's header row (case does not matter). Unique within the data structure. Do not start it with _: NADA uses such names internally.Label A readable label, shown in the catalog. Column type The column's role: indicator_id,indicator_name,geography,time_period,observation_value,periodicity,dimension,attribute,measureorannotation.Data type string,integer,float,double,dateorboolean. Optional.Time period format For the time_periodcolumn only, such asYYYY.Codelist For coded columns (geography, periodicity, dimension, attribute, measure): search for the codelist and select it. Its codes are listed below. Click Create.
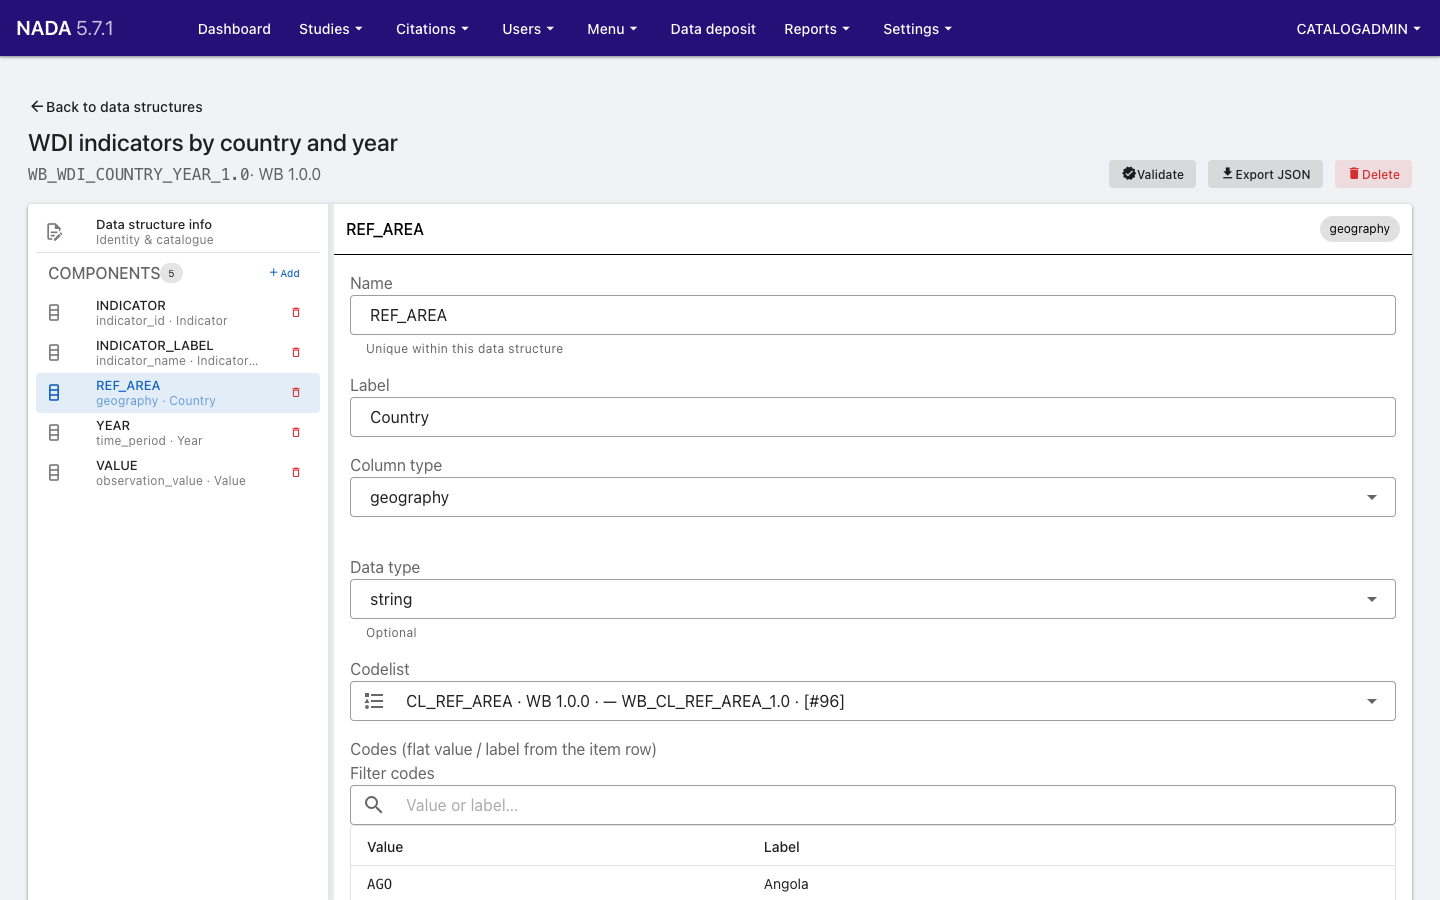
The sample's data structure has five columns:
| Name | Column type | Data type | Codelist |
|---|---|---|---|
INDICATOR | indicator_id | string | |
INDICATOR_LABEL | indicator_name | string | |
REF_AREA | geography | string | WB_CL_REF_AREA_1.0 |
YEAR | time_period (YYYY) | string | |
VALUE | observation_value | double |
Validate
Click Validate to check the data structure. NADA shows Validation passed. or lists the issues. A data structure needs exactly one indicator_id, one time_period and one observation_value column. A geography column is recommended.
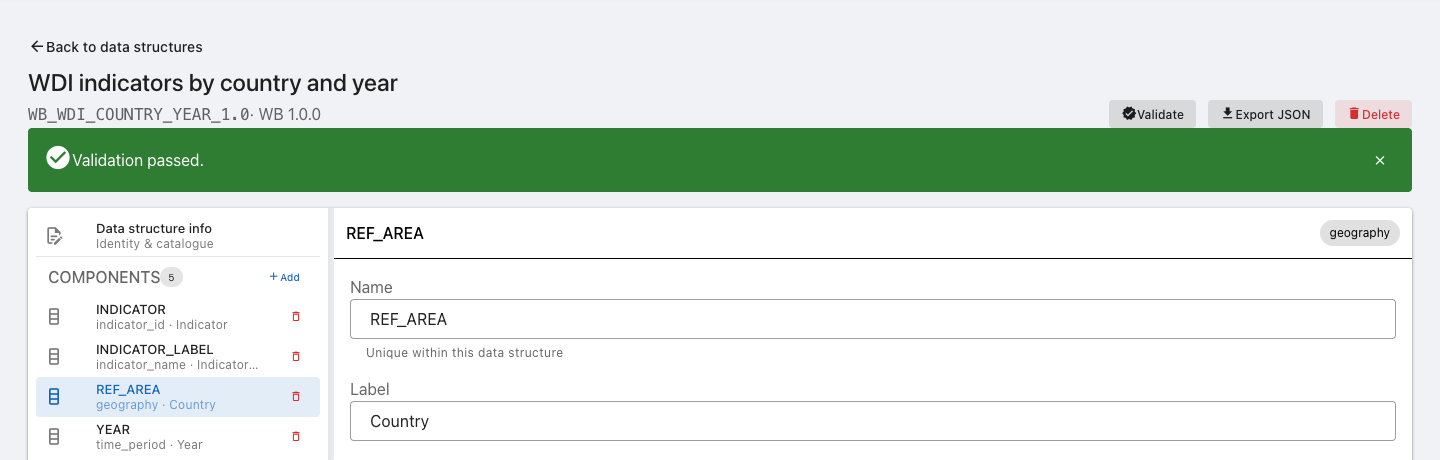
Click Export JSON to download the data structure, for example to import it into another catalog.
Versions, status and changes
A data structure has a status: Draft, Review, Published, Deprecated or Archived. While it is Published or Archived, it is locked: its fields and columns are read-only, and only Change status is available.
Changing a data structure affects every indicator that uses it
When a data structure's columns change, every indicator that uses it is marked Out of sync (sync pending). Its chart, table and Data API are hidden from the public catalog until it is resynced: open the indicator's Indicator data tab and click Resync, or upload its data again.
To make a larger change without affecting existing indicators, create a new version of the data structure and switch indicators to it one at a time. Switching an indicator to another data structure deletes its uploaded data, so upload the data again after switching.
Next steps
- Codelists
- Create an indicator in NADA: attach the data structure and upload data